class: left, middle, title-slide .title[ # Introduction to Bayesian Statistics ] .author[ ### Philipp K. Masur ] .date[ ### Workshop ] --- <style type="text/css"> .pull-left2 { float: left; width: 30%; } .pull-right2 { float: right; width: 60%; } .pull-left3 { float: left; width: 40%; padding-right: 5% } .pull-right3 { float: right; width: 40%; padding-left: 5% } .pull-left4 { float: left; width: 60%; } .pull-right4 { float: right; width: 30%; } .my-one-page-font { font-size: 17px; } .center2 { margin: 0; position: absolute; top: 50%; left: 50%; -ms-transform: translate(-50%, -50%); transform: translate(-50%, -50%); } </style> .pull-left3[   ] .pull-right3[   ] --- class: inverse, center, middle # Welcome Why are you interested in Bayesian Statistics? Any prior experience? --- # Expectations and overview .pull-left[ ### What we will cover - Bayes Theorem - Bayesian estimation using Markov Chains Monte Carlo methods - How to run (generalized) linear models using 'brms' - How to specify priors and interpret results - How to draw probabilistic inferences from results (using HDIs, ROPEs, etc.)) ] .pull-left[ ### What we will NOT cover - Introduction to R & Data Wrangling in R - Introduction to (generalized) linear models - Bayes factors - More complex models ] --- .pull-left[ ### Monday |Time |Topic | |:---------------|:-----------------------------| |9:00 - 9:30: |Welcome | |9:30 - 10:30: |An Introductory Example | |10:30 - 12:00: |Basics of Bayesian Statistics | |12:00 - 13:00: |R: Exercise I | |13:00 - 14:00: |Lunch Break | |14:00 - 14:45: |Markov Chain Monte Carlo | |14:45 - 15:30: |Bayesian Inference vs. NHST | |15:30 - 16:00: |Coffee Break | |16:00 - 17:00: |R: Exercise II | ] .pull-right[ ### Tuesday |Time |Topic | |:---------------|:-------------------------------------------| |9:00 - 10:00: |Subjective Beliefs and Knowledge Cumulation | |10:00 - 10:30: |Short recap of Day 1 | |10:30 - 11:30: |Simple and Multiple Regression | |11:30 - 13:00: |R: Exercise III | |13:00 - 14:00: |Lunch Break | |14:00 - 14:45: |Multilevel Regression | |14:45 - 15:30: |R: Exercise IV | |15:30 - 16:00: |Coffee Break | |16:00 - 17:00: |Q&A | ] --- # Other things... - This means a lot of theory, but also practical sessions! - First day: Understanding Bayesian Statistics - Second day: Doing stuff in R! - Please ask questions at all times - Try to keep up with the theory, but doing stuff in R will be more rewarding! --- # Literature .pull-left[ - My slides are based on these books by Kruschke and McElreath... - ... and their translation to "brms" by Salomon Kurz ([see here](https://bookdown.org/content/3686/)) - Great and comparatively simple introduction - Lots of examples (including R code) ] .pull-right[  ] --- # R Packages .pull-left2[ <img src="https://raw.githubusercontent.com/paul-buerkner/brms/master/man/figures/brms.png" width="150px" height="150px" padding-left="50px"><img src="https://easystats.github.io/bayestestR/logo.png" width="150px" height="150px" padding-left="50px"> <img src="https://raw.githubusercontent.com/stan-dev/logos/master/logo_tm.png" width="150px" height="150px" padding-left="50px"> ] .pull-right2[ - **brms**: Bayesian regression models using Stan - Main package - All types of models supported - **bayestestR** - set of functions to analyze and describe posterior distributions - ggplot-based visualizations - **tidybayes** - facilitates the use of tidy data with Bayesian models in R - **bayesplot** - plotting functions for use after fitting Bayesian models (typically with MCMC) - ggplot-based visualizations ] --- class: inverse, center, middle # An Introductory Example "The Geometry of Changing Beliefs" --- # Example: Covid-19 Rapid Test .pull-left[ Philipp is generally **a conscientious and orderly** person. Today, he has taken a Corona self-test as he regularly does. To his surprise, the **self-test is positive**. He remembers vaguely that such tests have **a sensitivity of 95%**, i.e. they are very good at picking up the disease. Thinking about it, he actually has been **coughing** a bit lately. He immediately isolates himself and wonders: <br> What is the probability of the rapid test result being correct? ] .pull-right[  ] --- # Intuition?  --- # Reality - We fail to acknowledge the true prevalence of the disease in the population. - Let's imagine for now that it is 4.8% in the population (an infection rate of 4800; currently it is rather 300, thus 0.3%)  --- # New knowledge = observing evidence - We have observed a positive test result - We know that the sensitivity and of such test is 95%: In 95 out of 100 cases, the test correctly identifies an infected person as positive.  --- # What else? - Such test also have a certain specificity (i.e., ability to correctly identify people who DON'T have the disease), which is also 95%. - This means, they produce false positives in 5% of the cases.  --- # What is the true probability?  --- # Non-Bayesian Thinking...  --- # Bayesian Thinking: Updating beliefs  --- # When should we use the Bayes Theorem?  --- # How does this translate into the formula?  --- # How does this translate into the formula?  --- # How does this translate into the formula?  --- # Multiplying probabilities  --- # With actual numbers  --- # The Bayes Theorem 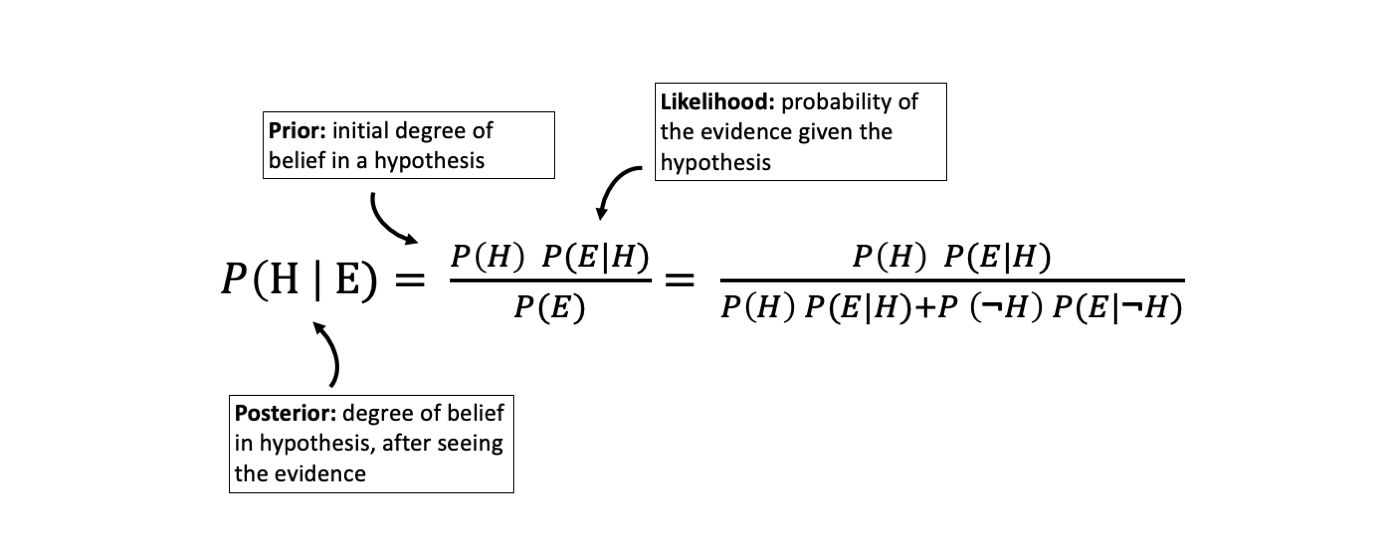 --- # Practical example: Naive Bayes classifier .pull-left[ - One of the simplest "algorithms" in automated text analysis (supervised machine learning) - Computes the prior probability ( _P_ ) for every category ( _c_ = outcome variable ) based on the training data set - Computes the probability of every feature ( _x_ ) to be a characteristic of the class ( _c_ ); i.e., the relative frequency of the feature in category - For every probability of a category in light of certain features ( _P(c|X)_ ), all feature probabilities ( _x_ ) are multiplied - The algorithm hence chooses the class that has highest weighted sum of inputs ] .pull-right[  ] --- # A Short History of Bayesian Statistics .pull-left[ - Thomas Bayes (1702-1761) was an English mathematician and presbyterian priest who came up with the idea of "inverse probability" - "An essay towards solving a problem in the doctrine of chances" includes a special cases of the Bayes theorem and was published posthum in 1764 by his friend Richard Price - Pierre-Simon Laplace (1749-1827) further develops the idea of "inverse probability" - 1980s: Increase in use of Bayesian statistics due to Markov Chain Monte Carlo methods ] .pull-right[  _(Thomas Bayes)_ ] --- class: inverse, center, middle # Basics of Bayesian Statistics "Combining prior beliefs and data" --- # Basic idea .pull-left2[ <br> `\(prior \rightarrow data \rightarrow posterior\)` <br> `\(p(\theta) \rightarrow D \rightarrow p(\theta|D)\)` <br> <img src="https://upload.wikimedia.org/wikipedia/commons/a/a0/Prior%2C_Likelihood%2C_Posterior_schematic.svg" width = "400" align="right" /> ] -- .pull-right2[ <br><br> - `\(\theta\)` is the relevant parameter that we are interested in (e.g., a effect, a hypothesis, a model...) - Bayes Theorem allow us to update a priori assumptions/beliefs `\(p(\theta)\)` about `\(\theta\)` based on collected data `\(D\)`. - The posterior probability `\(p(\theta|D)\)` reflects the updated assumptions about `\(\theta\)` given the (newly collected) data ] --- # What then is probability? .pull-left[ ### Bayesian A subjective belief >Bayesian probability statements are thus about states of mind over states of the world, and not about states of the world per se. Indeed, whatever one believes about determinism or chance in social processes, the meaningful uncertainty is that which resides in our brains, upon which we will base decisions and actions. (Jackman, 2009, S. 7) ] .pull-right[ ### Frequentist A long-run frequency >At its core, frequentist statistics is about repeatability and gathering more data. The frequentist interpretation of probability is the long-run frequency of repeatable experiments. For example, saying that the probability of a coin landing heads being 0.5 means that if we were to flip the coin enough times, we would see heads 50% of the time. (Dilipkumar, 2021) ] --- # Frequentist statistics in short... .pull-left[ - The "classic" statistical framework - Is based on the idea of repeated sampling from a population - Population parameters are fixed, actually exist - Probability refers to the long-run frequency of a given event - Data are random, result from sampling a fixed population distribution ] .pull-right[ <img src="slides_01_files/figure-html/unnamed-chunk-5-1.png" width="100%" /> ] --- # Sampling from the population <img src="slides_01_files/figure-html/unnamed-chunk-6-1.png" width="100%" /> --- # Parameter distribution .pull-left[ <img src="slides_01_files/figure-html/unnamed-chunk-7-1.png" width="100%" /> ] .pull-right[ - According to the central limit theorem, the means are distributed around the true population parameter `\(M\)` = 680. - The standard error, defined as `\(SE = SD(x)/\sqrt(n-1)\)` and which we can computed based on a single sample, is an estimate for the variance of this mean distribution - In our first sample, the standard error is `\(SE\)` = `\(164/\sqrt(50-1)\)` = 27.3 ] --- # What is the p-value then? .pull-left[ - The p-value tells you how often you would expect to see a test statistic as extreme or more extreme than the one calculated by your statistical test if the null hypothesis of that test was true <img src="https://media.tenor.com/tvFWFDXRrmMAAAAd/blow-mind-mind-blown.gif" width="250" style = "padding-left: 4em;"> - We thus investigate the plausibility of the data given `\(H_0\)`, but NOT the plausibility of the hypothesis given the data! ] .pull-right[  ] --- # (Critique of the) Frequentist approach - Null hypothesis significance tests (NHST) focuses on the wrong probability: - `\(P(D|H_0)\)` instead of `\(P(H|D)\)` <br> - Comparatively difficult (and thus often wrong) interpretation of the parameters of interest (p-values, confidence intervals) - No accumulation of knowledge in the statistical model (i.e., no incorporation of prior information) - The concept of Frequentist probability can only be applied to standardized, repeatable phenomena --- # Conceptual Framework of Bayesian Data Analysis .pull-left2[ <br> `\(prior \rightarrow data \rightarrow posterior\)` <br> `\(p(\theta) \rightarrow D \rightarrow p(\theta|D)\)` <br> <img src="https://upload.wikimedia.org/wikipedia/commons/a/a0/Prior%2C_Likelihood%2C_Posterior_schematic.svg" width = 400 align="right" /> ] .pull-right2[ <br> > Bayesian data analysis has two foundational ideas. The first idea is that Bayesian inference is *reallocation of credibility* across possibilities. The second foundational idea is that the possibilities, over which we allocate credibility, are *parameter values in meaningful mathematical models*. (Kruschke, 2015, p. 15) ] --- # Reallocation of probability: The classical coin toss .pull-left[ - We are going to use the classical coin toss example to exemplify the interaction between "prior" belief, data, and "posterior" belief. - In Bayesian statistics, parameters of interest (such as the probability of heads) are treated as random variables, which can be described with a probability distribution (e.g., via `\(Beta(\alpha, \beta)\)`) ] .pull-right[  ] --- # The coin toss: Prior Assumptions .pull-left[ - We don't even need data to describe this distribution, the probability is simply our degree of belief. - In this case, we could assume that a fair coin has a high probability of showing heads 50% of the time and a lesser probability to show heads or tails more often. ```r # Computing a prior d1 <- tibble(prob = seq(0, 1, by = .001), prior = dbeta(prob, 30, 30)) %>% mutate(prior = prior/sum(prior)) # Plot d1 %>% ggplot(aes(x = prob, y = prior)) + geom_line(color = "red", size = 1.25) + theme_minimal() + #theme(panel.grid = element_blank()) + labs(x = expr(theta), y = "", title = "Prior", subtitle = "Beta(30, 30)") ``` ] .pull-right[ <img src="slides_01_files/figure-html/coin-out1-1.png" width="100%" /> ] --- # The coin toss: Understanding the data .pull-left[ - We toss a coin and are interested in the probability of it showing "heads" (vs. "tails"). Let's imagine we toss it 10 times and heads comes up 4 times. - Here, we denote y = 1 for "heads" (or success) and y = 0 for "tails" (failure). ```r # Coin toss set.seed(1) toss <- sample(c("tails", "heads"), size = 10, replace = T) # Frequency Plot ggplot(NULL, aes(x = toss)) + geom_bar(fill = "steelblue", width = .5) + scale_y_continuous(n.breaks = 5, limits = c(0, 8)) + theme_minimal() + labs(x = "") ``` ] .pull-right[ <img src="slides_01_files/figure-html/coin-out2-1.png" width="100%" /> ] --- # The coin toss: The likelihood .pull-left[ - The likelihood is a mathematical formula that specifies the plausibility of the data - In our example, the likelihood can be expressed as a binomial distribution: <br> `\(P(y|n, p) = \frac{n!}{y!(n-y)!}p^y(1-p)^{n-y}\)` `\(P(4|10, 0.5) = \frac{10!}{4!(10-4)!}0.5^4(1-0.5)^{10-4} = 0.2050781\)` ] .pull-right[ ```r dbinom(x = 4, size = 10, prob = 0.5) ``` ``` [1] 0.2050781 ``` ```r dbinom(x = 4, size = 10, prob = c(.25, .5, .75)) ``` ``` [1] 0.1459980 0.2050781 0.0162220 ``` ] --- # The coin toss: The likelihood .pull-left[ ```r # Compute likelihood d1 <- d1 %>% mutate(likelihood = dbinom(x = 4, size = 10, prob = prob), likelihood = likelihood/sum(likelihood)) # Plot d1 %>% ggplot(aes(x = prob, y = likelihood)) + geom_line(color = "darkblue", size = 1.25) + theme_minimal() + labs(x = expr(theta), y = "", title = "Likelihood", subtitle = expr(paste("Binomial(4, 10, ", theta, ")"))) ``` ] .pull-right[ <img src="slides_01_files/figure-html/coin-out3-1.png" width="100%" /> ] --- # The coin toss: Computing the posterior distribution `\(Posterior = Prior * Likelihood\)` `\(P(\theta|y) = P(\theta)*P(y|\theta)\)` `\(P(\theta|y) = Beta(\alpha, \beta) * Binomial(y, n, \theta)\)` `\(P(\theta|y) = Beta(y + \alpha, n - y + \beta)\)` `\(P(\theta|y) = Beta(4 + 30, 10 - 4 + 30)\)` -- <br> **Note:** This works because beta and binomial distribution are from the same family of distributions. The beta distribution is what we call a "conjugate" prior to the binomial distribution! --- # The coin toss: Computing the posterior distribution .pull-left[ ```r d1 <- d1 %>% mutate(posterior = (prior*likelihood)/sum(prior*likelihood)) d1 %>% gather(key, value, -prob) %>% mutate(factor(key, levels = c("prior", "likelihood", "posterior"))) %>% ggplot(aes(x = prob, y = value, color = key)) + geom_line(size = 1.25) + scale_color_manual(values = c("darkblue", "black", "red")) + theme_minimal() + labs(x = expr(theta), y = "", color = "", title = "Prior, likelihood, and posterior") + theme(legend.position = "bottom") ``` ] .pull-right[ <img src="slides_01_files/figure-html/coin-out4-1.png" width="100%" /> ] --- # Influence of prior on posterior .pull-left2[ - One of the benefits of Bayesian statistics is that we can use different priors and compare results - Differently *informative* priors have a differently strong influence on the posterior distribution. ] .pull-right2[ <img src="slides_01_files/figure-html/unnamed-chunk-9-1.png" width="100%" /> ] --- # Influence of sample size .pull-left2[ - When we collect larger samples, the influence of the prior will be overwhelmed by the data - Our estimation naturally thereby becomes more precise ] .pull-right2[ <img src="slides_01_files/figure-html/unnamed-chunk-10-1.png" width="100%" /> ] --- # What to do with the posterior distribution? .pull-left[ - Well, we can summarize it much like any distribution and thereby gain an understanding of our updated probability - The most frequent `\(\theta\)` value is the most probably value in the distribution - We could define boundaries for the most probable values - and many more things (more on that later) ] .pull-right[ <img src="slides_01_files/figure-html/unnamed-chunk-11-1.png" width="100%" /> ] --- # Summarizing the Logic of Bayesian Inference - Bayesian inference is reallocation of credibility across possibilities - The distribution of credibility initially reflects prior knowledge about the possibilities (which can be quite vague or very specific) - When new data are observed, the credibility is re-allocated - Possibilities that are consistent with the data garner more credibility, while possibilities that are not consistent with the data lose credibility: we can hence test several prior beliefs - Bayesian analysis is the mathematics of re-allocating credibility in a logically coherent and precise way --- # Analytic challenges: Why can't we do it always like that? - Many research application are not analytically solvable - For example, when we investigate continuous data, the denominator in the Bayes Theorem is often not analytically solvable: `\(P(\theta|y) = \frac{p(y|\theta)P(\theta)}{P(y)} = \frac{L(\theta,y)P(\theta)}{\int P(y|\theta)P(\theta)d\theta}\)` - Different solutions exits: - Conjugate priors (what we just did in the coin example, not very flexible) - Numeric grid approximation of the integral (doesn't work if the model has many parameters) - **Markov Chain Monte Carlo Methods** --- class: inverse, center, middle # Markov Chain Monte Carlo "Simulating caterpillars" --- # Basic Idea - Whenever we cannot produce a posterior distribution analytically, we can **approximate** its form using a method called Markov Chains Monte Carlo (MCMC) - Approximation means that an algorithm produces a large number of `\(\theta\)` values from the posterior distribution (i.e., actual data that looks like the posterior distribution!) - This heap of representative `\(\theta\)` values can then be used to estimate the central tendency of the posterior, highest density intervals (HDI) and many more things - Bayesian, simulation-based inference is thus based on the repeated sampling from the posterior distribution - The posterior is hence produced by randomly generating a lot of values from it. --- # Approximating a distribution with a (large) sample .pull-left[ - The basic idea should be well know: e.g., when we sample a subset of people from a population to estimate underlying tendencies in the population - Here, we sample from a mathematically defined distribution (e.g., the posterior probability distribution) - Naturally, the larger the sample, the smoother the resulting histogram and the closer the sample is to the exact distribution ] .pull-right[ <img src="slides_01_files/figure-html/unnamed-chunk-12-1.png" width="100%" /> ] --- # Sampling from the distribution <img src="slides_01_files/figure-html/unnamed-chunk-13-1.png" width="100%" /> --- # Example <img src="slides_01_files/figure-html/unnamed-chunk-14-1.png" width="100%" /> ```r set.seed(42) t <- replicate(rbeta(1, 14, 7), n = 100) t[1] ``` ``` [1] 0.7299523 ``` --- # Example <img src="slides_01_files/figure-html/unnamed-chunk-16-1.png" width="100%" /> ```r t[1:2] ``` ``` [1] 0.7299523 0.6227095 ``` --- # Example <img src="slides_01_files/figure-html/unnamed-chunk-18-1.png" width="100%" /> ```r t[1:4] ``` ``` [1] 0.7299523 0.6227095 0.5876640 0.6175111 ``` --- # Example <img src="slides_01_files/figure-html/unnamed-chunk-20-1.png" width="100%" /> ```r t[1:10] ``` ``` [1] 0.7299523 0.6227095 0.5876640 0.6175111 0.6789558 0.4542324 0.6776384 [8] 0.3634036 0.6739552 0.4885336 ``` --- # Example <img src="slides_01_files/figure-html/unnamed-chunk-22-1.png" width="100%" /> ```r t[1:25] ``` ``` [1] 0.7299523 0.6227095 0.5876640 0.6175111 0.6789558 0.4542324 0.6776384 [8] 0.3634036 0.6739552 0.4885336 0.8156487 0.6985190 0.6820710 0.5872489 [15] 0.6991303 0.9097260 0.4860653 0.7016298 0.6864694 0.5029334 0.7153275 [22] 0.6961074 0.6103759 0.7380649 0.6109734 ``` --- # Example <img src="slides_01_files/figure-html/unnamed-chunk-24-1.png" width="100%" /> ```r t[1:50] ``` ``` [1] 0.7299523 0.6227095 0.5876640 0.6175111 0.6789558 0.4542324 0.6776384 [8] 0.3634036 0.6739552 0.4885336 0.8156487 0.6985190 0.6820710 0.5872489 [15] 0.6991303 0.9097260 0.4860653 0.7016298 0.6864694 0.5029334 0.7153275 [22] 0.6961074 0.6103759 0.7380649 0.6109734 0.5779003 0.5305604 0.7347250 [29] 0.6045728 0.8475548 0.7534631 0.7604764 0.6624323 0.6421302 0.7076755 [36] 0.5705447 0.7473325 0.8135962 0.6138742 0.7563110 0.7154348 0.5845931 [43] 0.6278671 0.7533975 0.5863136 0.6560934 0.6334922 0.5813874 0.6560848 [50] 0.6324634 ``` --- # Example <img src="slides_01_files/figure-html/unnamed-chunk-26-1.png" width="100%" /> ```r t[1:100] ``` ``` [1] 0.7299523 0.6227095 0.5876640 0.6175111 0.6789558 0.4542324 0.6776384 [8] 0.3634036 0.6739552 0.4885336 0.8156487 0.6985190 0.6820710 0.5872489 [15] 0.6991303 0.9097260 0.4860653 0.7016298 0.6864694 0.5029334 0.7153275 [22] 0.6961074 0.6103759 0.7380649 0.6109734 0.5779003 0.5305604 0.7347250 [29] 0.6045728 0.8475548 0.7534631 0.7604764 0.6624323 0.6421302 0.7076755 [36] 0.5705447 0.7473325 0.8135962 0.6138742 0.7563110 0.7154348 0.5845931 [43] 0.6278671 0.7533975 0.5863136 0.6560934 0.6334922 0.5813874 0.6560848 [50] 0.6324634 0.7083591 0.6446488 0.5944772 0.7473950 0.4889095 0.6261296 [57] 0.5300497 0.5474479 0.5756988 0.7805258 0.6771239 0.5889181 0.7712239 [64] 0.7275841 0.5945869 0.5691513 0.6099034 0.7641396 0.7863684 0.4540306 [71] 0.6357857 0.6562502 0.6806494 0.7960457 0.5904602 0.6915907 0.6877000 [78] 0.5456113 0.5616302 0.7203318 0.5853090 0.7874998 0.7615160 0.7896496 [85] 0.8226241 0.6572537 0.5849233 0.5050914 0.5291110 0.7763918 0.7409353 [92] 0.6542196 0.7144254 0.6808159 0.6442902 0.6525917 0.6695922 0.6539146 [99] 0.7213427 0.7233895 ``` --- # Example <img src="slides_01_files/figure-html/unnamed-chunk-28-1.png" width="100%" /> -- <img src="slides_01_files/figure-html/unnamed-chunk-29-1.png" width="100%" /> - Even when we resample from the same distribution, in the long-run, the data will converge towards the target distribution - Here, we can already see one approach to "check" whether the chains have converged: If they form caterpillar plots like the one at the bottom, and the two chains overlap significantly, they both have converged perfectly. --- # Markov Chain Monte Carlo - Markov chain Monte Carlo (MCMC) methods work in a similar type of way - They comprise a class of algorithms for sampling from a probability distribution - By constructing a Markov chain that has the desired distribution as its equilibrium distribution, one can obtain a sample of the desired distribution by recording states from the chain. - The more steps that are included, the more closely the distribution of the sample matches the actual desired distribution. - Various algorithms exist for constructing chains exist: - Metropolis Algorithm - Metropolis–Hastings algorithm - Gibbs Sampling - Hamiltonian Monte Carlo (implemented in `brms`) - No-U-Turn Sampler (NUTS, also implemented in `brms`) --- # A Simple Metropolis Algorithm (see McElreath, chapter 7.2) .pull-left[ - King Markov is a benevolent autocrat of an island kingdom - The king’s island kingdom is displayed in the Figure on the right, with the islands numbered by their relative population sizes - He wants to visit each island in His kingdom from time to time. - Everyone agreed that the king should visit each island in proportion to its population size, visiting the largest island 10 times as often as the smallest, for example. - The Good King Markov wanted a way to fulfill his obligation without planning his travels months ahead of time and further insisted that he only move among adjacent islands, to minimize time spent on the water (sea monsters, etc.) ] .pull-right[ 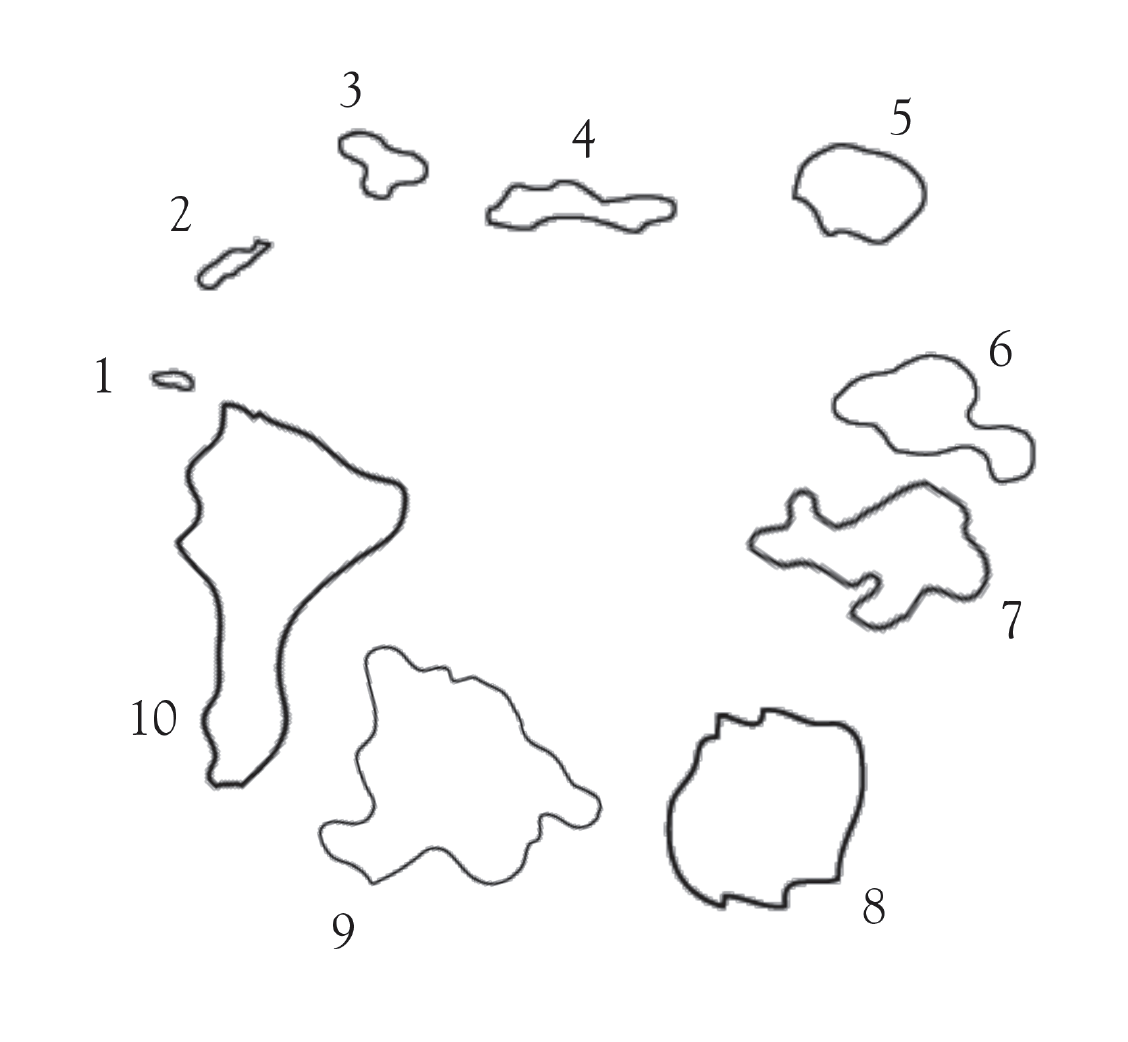 ] --- # Theory of the travel computation His advisor engineered a clever solution to these demands and here's how it works: 1. Wherever the King is, each week he decides between staying put for another week or moving to one of the two adjacent islands. To decide his next move, he **flips a coin**. 2. If the coin turns up heads, the King considers moving to the adjacent island clockwise around the archipelago. If the coin turns up tails, he considers instead moving counterclockwise. Call the island the coin nominates **the proposal** island. 3. Now, to see whether or not he moves to the proposal island, King Markov counts out **a number of seashells** equal to the relative population size of the proposal island. So for example, if the proposal island is number 9, then he counts out 9 seashells. Then he also counts out **a number of stones** equal to the relative population of the current island. So for example, if the current island is number 10, then King Markov ends up holding 10 stones, in addition to the 9 seashells. 4. When there are **more seashells than stones**, King Markov always moves to the proposal island. But if there are fewer shells than stones, he discards a number of stones equal to the number of shells. So for example, if there are 4 shells and 6 stones, he ends up with 4 shells and 6 - 4 = 2 stones. Then he places the shells and the remaining stones in a bag. He reaches in and **randomly pulls out one object**. If it is a shell, he moves to the proposal island. Otherwise, he stays put another week. As a result, the probability that he moves is equal to the number of shells divided by the original number of stones. --- # Computation of King Markov's travel route .pull-left[ ```r set.seed(7) num_days <- 5e4 positions <- rep(0, num_days) current <- 4 for (i in 1:num_days) { # record current position positions[i] <- current # flip coin to generate proposal proposal <- current + sample(c(-1, 1), size = 1) # now make sure he loops around from 7 back to 1 if (proposal < 1) proposal <- 7 if (proposal > 7) proposal <- 1 # move? prob_accept_the_proposal <- proposal/current current <- ifelse(runif(1) < prob_accept_the_proposal, proposal, current) } ``` ] .pull-right[ <img src="slides_01_files/figure-html/unnamed-chunk-31-1.png" width="100%" /> ] --- # Resulting distribution of time on each island .pull-left[ <img src="slides_01_files/figure-html/unnamed-chunk-32-1.png" width="100%" /> ] .pull-right[ - Even though the King seems to move randomly across the archipel, in the end, he visits each island proportional to its population size - This is of course a fictitious, somewhat artificial example, but it shows that the algorithm works - Drawing from a posterior distribution is - to a certain degree (slightly more complex) similar to such a random walk ] --- # Preliminary summary on MCMC - Whenever we cannot solve the denominator of the Bayes Theorem analytically, we resort to MCMC methods to approximate the posterior distribution - The result of a Bayesian analysis is thus almost always a number of `\(\theta\)` values whose distribution is representative of the posterior distribution - This posterior can then be analyzed and used for inferences - Because it is an actual data set with certain properties, the possibilities for different types of inferences are practically endless -- <br> **Note:** An important step in Bayesian simulation-based inference is to check whether the MCMC chains actually "converged". We will come back to MCMC diagnostics later as those can be best understood based on an actual proper example! --- class: inverse, center, middle # Bayesian Inference vs. NHST "Summarizing the posterior" --- # Applying Bayes to linear regression <br><br> **Frequentist:** There is a single "true" line of best fit, and I'll give my best estimate of it. <br> **Bayesian:** There is a distribution of lines of fit, some more plausible than others, and I'll give you samples from that distribution. --- # Proper (Communication) Example - In 2019, I conducted an experiment in which participants saw different social media feeds (Masur, DiFranzo & Bazarova, 2021). The feeds varied with regard to the amount of visual disclosure in a) posts (norm) and b) profile pictures (profile). - Afterwards, participants were asked to indicate their perception of the norm to disclose the self and how likely they would be to disclose themselves on such a social media platform. - In a first step, let's have a look at the relationship between perceptions and behaviors --- # Getting to know the data .pull-left[ ```r url <- "https://osf.io/kfm6x/download" d <- read.csv(url,header=TRUE, na.strings="NA") %>% as_tibble %>% select(norm, profile, contains("NOR"), contains("BEH")) (d %<>% mutate(id = 1:n(), perceptions = rowMeans( d %>% select(contains("NOR"), -norm) ), behavior = rowMeans( d %>% select(contains("BEH")) )) %>% select(norm, profile, perceptions, behavior)) ``` ``` # A tibble: 677 × 4 norm profile perceptions behavior <chr> <chr> <dbl> <dbl> 1 n0 p20 NA 5 2 n20 p20 6.75 6 3 n0 p0 6 6.5 4 n20 p80 6.08 6 5 n20 p20 7 7 6 n0 p80 NA 3.5 7 n20 p20 3.17 1.83 8 n20 p80 5.83 5.5 9 n0 p80 1 1.5 10 n80 p80 4.75 4.67 # … with 667 more rows ``` ] .pull-right[ <img src="slides_01_files/figure-html/unnamed-chunk-34-1.png" width="100%" /> ] --- # Standardization - As in frequentist linear regression analysis, it can be meaningful to standardize our variables upfront - Although standardization is not obligatory, it is often very meaningful in Bayesian analyses because - algorithms converge more easily with smaller data ranges - we often can quantify our prior beliefs better on a standardized scale (e.g., `\(r = .10\)`) ```r d$perceptions_std = scale(d$perceptions) %>% as.vector d$behavior_std = scale(d$behavior) %>% as.vector d %>% select(perceptions_std, behavior_std) %>% psych::describe() ``` ``` vars n mean sd median trimmed mad min max range skew kurtosis se perceptions_std 1 660 0 1 0.24 0.05 1.09 -1.97 1.56 3.52 -0.42 -0.97 0.04 behavior_std 2 674 0 1 0.02 -0.02 1.30 -1.55 1.97 3.52 0.14 -1.18 0.04 ``` --- # Frequentist linear regression .pull-left2[ We can define this model with the following formula: `\(y_i = \beta_0 + \beta_1x_i + \epsilon_i\)` or alternatively as: `\(y_i \sim Normal(\mu_i, \sigma)\)` `\(\mu_i = \beta_0 + \beta_1x_i\)` ] .pull-right2[ ```r m_freq <- lm(behavior_std ~ perceptions_std, data = d[1:100,]) summary(m_freq) ``` ``` Call: lm(formula = behavior_std ~ perceptions_std, data = d[1:100, ]) Residuals: Min 1Q Median 3Q Max -1.96193 -0.68264 -0.08681 0.81878 2.55285 Coefficients: Estimate Std. Error t value Pr(>|t|) (Intercept) -0.03178 0.10001 -0.318 0.751372 perceptions_std 0.39863 0.09804 4.066 0.000101 *** --- Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1 Residual standard error: 0.9568 on 92 degrees of freedom (6 observations deleted due to missingness) Multiple R-squared: 0.1523, Adjusted R-squared: 0.1431 F-statistic: 16.53 on 1 and 92 DF, p-value: 0.0001007 ``` ] --- # Visualization .pull-left[ ```r (p_freq <- ggplot(d[1:100,], aes(x = perceptions_std, y = behavior_std)) + geom_point(alpha = .5, size = 2) + geom_smooth(method = "lm", color = "steelblue", ) + theme_classic() + labs(title = "One line equals the best fit", subtitle = "Frequentist Estimation", x = "Norm Perceptions", y = "Self-Disclosure")) ``` ] .pull-right[ <img src="slides_01_files/figure-html/ex1-out-1.png" width="100%" /> ] --- # Bayesian Linear regression .pull-left2[ This model can be expressed with the following formula *Likelihood:* `\(y_i \sim Normal(\mu_i, \sigma)\)` `\(\mu_i = \beta_0 + \beta_1x_i\)` *Prior (weakly informative)*: `\(\beta_0 \sim Normal(0, 10)\)` `\(\beta_1 \sim Normal(0, 10)\)` `\(\sigma \sim Uniform(0, 10)\)` ] .pull-right2[ ```r m_bay <- brm(formula = behavior_std ~ 1 + perceptions_std, data = d[1:100,], seed = 2) ``` ```r summary(m_bay) ``` ``` Family: gaussian Links: mu = identity; sigma = identity Formula: behavior_std ~ 1 + perceptions_std Data: d[1:100, ] (Number of observations: 94) Draws: 4 chains, each with iter = 2000; warmup = 1000; thin = 1; total post-warmup draws = 4000 Population-Level Effects: Estimate Est.Error l-95% CI u-95% CI Rhat Bulk_ESS Tail_ESS Intercept -0.03 0.10 -0.24 0.17 1.00 3554 2729 perceptions_std 0.40 0.10 0.20 0.59 1.00 4461 3161 Family Specific Parameters: Estimate Est.Error l-95% CI u-95% CI Rhat Bulk_ESS Tail_ESS sigma 0.97 0.07 0.84 1.13 1.00 3823 2788 Draws were sampled using sampling(NUTS). For each parameter, Bulk_ESS and Tail_ESS are effective sample size measures, and Rhat is the potential scale reduction factor on split chains (at convergence, Rhat = 1). ``` ] --- # Visualization .pull-left[ ```r # Extract posterior distributions draws <- as_draws_df(m_bay) # Plot regression lines (p_bay <- draws %>% sample_n(size = 200) %>% ggplot() + geom_abline(aes(intercept = b_Intercept, slope = b_perceptions_std, group = .draw), color = "grey50", size = 1/4, alpha = .3) + geom_abline(aes(intercept = -0.0534, slope = 0.394, group = .draw), color = "steelblue", size = 1) + geom_point(data = d[1:100,], aes(x = perceptions_std, y = behavior_std), size = 2, alpha = .5) + labs(title = "Multiple credible regression lines", subtitle = "Bayesian Estimation", x = "Norm Perceptions", y = "Self-Disclosure") + theme_classic()) ``` ] .pull-right[ <img src="slides_01_files/figure-html/ex2-out-1.png" width="100%" /> ] --- # Visualization: Many possibilities! <img src="slides_01_files/figure-html/unnamed-chunk-40-1.png" width="100%" /> --- # So what is the difference? .pull-left[ <img src="slides_01_files/figure-html/unnamed-chunk-41-1.png" width="100%" /> ] .pull-right[ <img src="slides_01_files/figure-html/unnamed-chunk-42-1.png" width="100%" /> ] --- # The Posterior .pull-left[ - By using Bayesian simulation-based estimation, we get thousands of "lines" (or in other words, values) for our parameter of interest - Some are more probable than others and we can visualize this distribution with a simple histogram - Inference then means to summarize this distribution in one way or the other ] .pull-right[ <img src="slides_01_files/figure-html/unnamed-chunk-43-1.png" width="100%" /> ] --- # Highest density interval (HDI) .pull-left[ ```r draws %>% ggplot(aes(x = b_perceptions_std, y = 0)) + stat_histinterval(point_interval = mode_hdi, .width = .95, fill = "steelblue", slab_color = "grey92", breaks = 40, slab_size = .2, outline_bars=T) + annotate(geom = "text", x = .394, y = .1, size = 5, label = "Mode = .394", color = "white") + scale_y_continuous(NULL, breaks = NULL) + labs(title = "The posterior distribution", x = expression(beta[1]~(slope))) + theme_tidybayes() ``` We will learn about Bayesian inference in a second, but let's first revisit our MCMC draws! ] .pull-right[ <img src="slides_01_files/figure-html/ex3-out-1.png" width="100%" /> ] --- # MCMC convergence diagnostic - Remember: Whenever we use a MCMC algorithm, we need to determine whether it "converged" - Goals: - The sampled values of the chain should be representativ of the target distribution (i.e., non-determined by the start value and the chain should not get stuck) - The chain should be sufficiently long to generate sufficiently stable estimations - Efficiency (time and computing power) - Convergence checks: - Graphical checks - Statistical paramters --- # Graphic Checks: Traceplots .pull-left[ - Visual inspection of the chains - When several chains are estimated (what we often do), check overlap and mix - Chains should not get stuck at one place for longer ```r library(bayesplot) draws2 <- as_draws_df(m_bay, inc_warmup = T) mcmc_trace(draws2, pars = c("b_Intercept", "b_perceptions_std"), n_warmup = 1000, facet_args = list(nrow = 2)) + theme_bw() + theme(panel.grid = element_blank()) ``` - On the right, I also plotted the "warm-up phase". MCMC chains take a while to converge, which is why we always sample more and then cut the first part. ] .pull-right[ <img src="slides_01_files/figure-html/mcmc1-out-1.png" width="100%" /> ] --- # Graphic Checks: Traceplots This is how they should look like: <img src="slides_01_files/figure-html/unnamed-chunk-44-1.png" width="100%" /> --- # Graphic Checks: Traceplots How they should NOT like like... 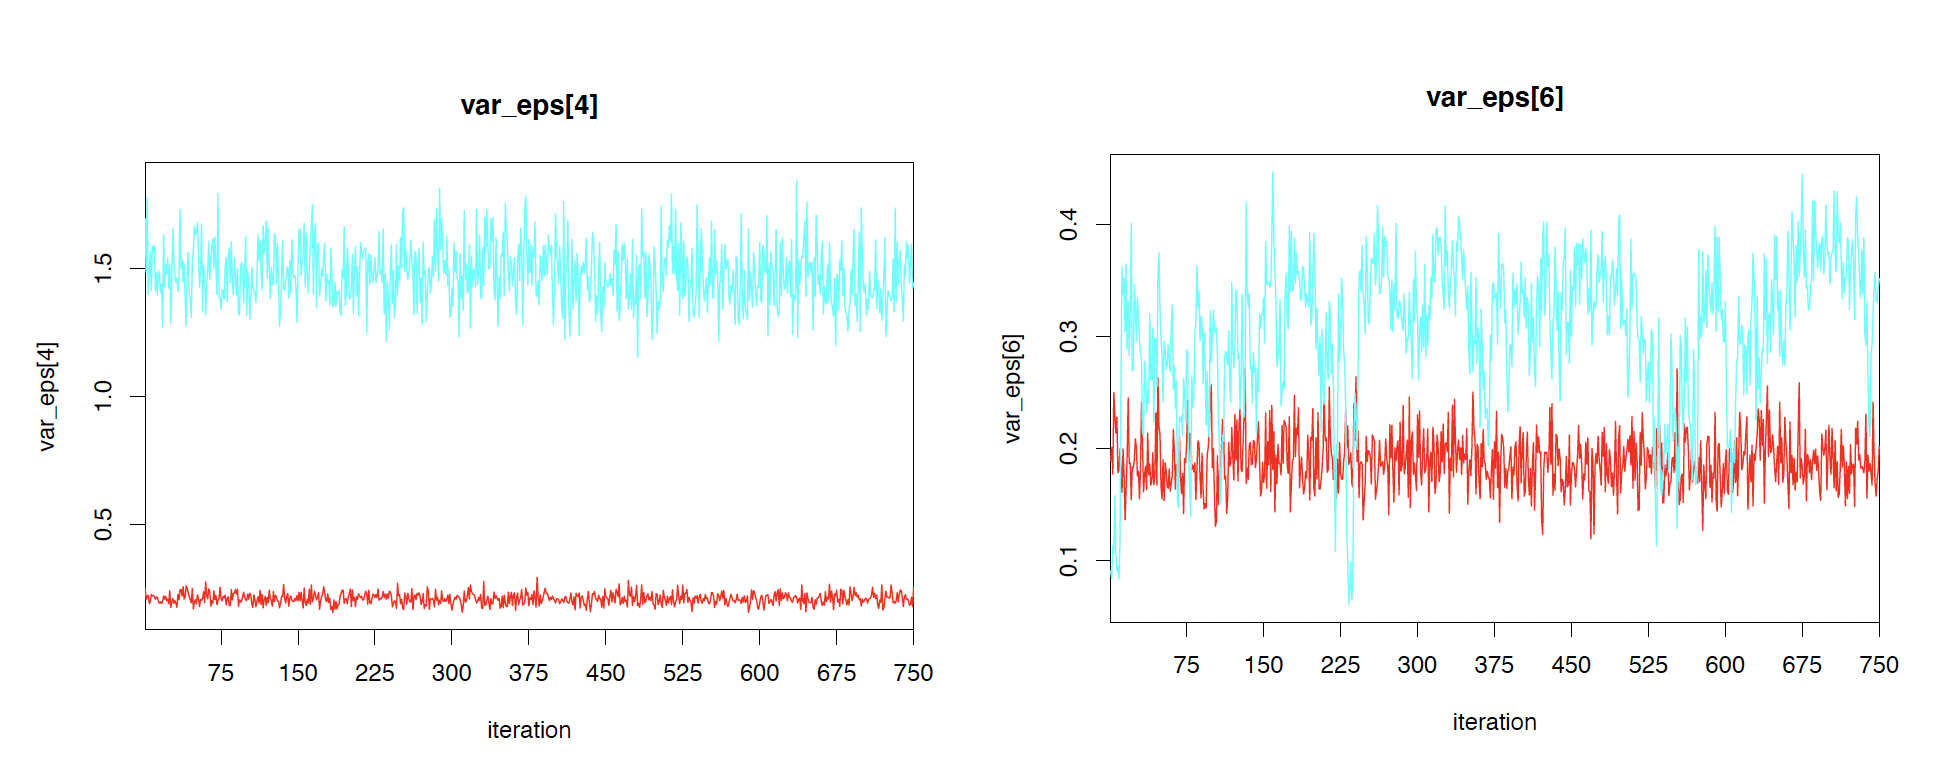 --- # Potential Scale Reduction Factor .pull-left4[ - Also known as Gelman-Rubin-Statistic or "shrink factor" - A parameter for the variance between the chains in relation to the variance within the chain `\(\widehat{R} = \sqrt{\frac{\widehat{Var}(\theta|y)}{W}}\)` - `\(\widehat{Var}(\theta|y)\)`: Estimator for the posterior variance of `\(\theta\)` - `\(W\)`: Variance within chains - If chains converge, the differences between chains should be on average as great as within chains: `\(\widehat{R} = 1\)` ] .pull-right4[ ```r rhat(m_bay) %>% as_tibble(rownames = "par") ``` ``` # A tibble: 5 × 2 par value <chr> <dbl> 1 b_Intercept 1.00 2 b_perceptions_std 1.00 3 sigma 1.00 4 lprior 1.00 5 lp__ 1.00 ``` No problems in our model! ] --- # Simulation Efficiency - Samplings from a markov chains are not independent! - The stronger the dependency (auto-correlation) between consecutive values, the slower the chain explores the parameter space - Auto correlation between samples is a nuisance that affects the effeciency of the simulations; stronger dependency means more iterations are necessary --- # Autocorrelation .pull-left4[ ```r mcmc_acf(draws, pars = c("b_Intercept", "b_perceptions_std"), lags = 40) + theme_tidybayes() ``` <img src="slides_01_files/figure-html/unnamed-chunk-46-1.png" width="100%" /> ] .pull-right4[ - That’s just what we like to see: nice L-shaped autocorrelation plots. - Those are the kinds of shapes we would expect when we have reasonably large effective samples. ] --- # Effective sample size (ESS) .pull-left2[ - Another parameter of simulation efficiency - How much independent information is in the auto-correlated chains? - How big should the ESS be? - Depends on the statistic of interest (higher ESS for interval estimations, tails of the posterior distribution compared to central tendencies) - Kruschke (2015) recommends at least 10.000 for interval limits ] .pull-right2[ ``` Family: gaussian Links: mu = identity; sigma = identity Formula: behavior_std ~ 1 + perceptions_std Data: d[1:100, ] (Number of observations: 94) Draws: 4 chains, each with iter = 2000; warmup = 1000; thin = 1; total post-warmup draws = 4000 Population-Level Effects: Estimate Est.Error l-95% CI u-95% CI Rhat Bulk_ESS Tail_ESS Intercept -0.03 0.10 -0.24 0.17 1.00 3554 2729 perceptions_std 0.40 0.10 0.20 0.59 1.00 4461 3161 Family Specific Parameters: Estimate Est.Error l-95% CI u-95% CI Rhat Bulk_ESS Tail_ESS sigma 0.97 0.07 0.84 1.13 1.00 3823 2788 Draws were sampled using sampling(NUTS). For each parameter, Bulk_ESS and Tail_ESS are effective sample size measures, and Rhat is the potential scale reduction factor on split chains (at convergence, Rhat = 1). ``` ] --- # Thinning .pull-left[ - If there is too much auto-correlation, we can "thin" the chains - Only every `\(k\)` sampling of a chain will be saved and used for the posterior - reduces auto correlation, but efficiency remains the same - reduces effective sample size ] .pull-right[ ```r brm(formula = behavior_std ~ 1 + perceptions_std, data = d[1:100,], warmup = 1000, iter = 10000, # higher iterations thin = 4, # only every 4th draw seed = 2) ``` ] --- class: inverse, center, middle # Bayesian Inference vs. NHST "HDIs, ROPES, percentages..." --- # Bayesian Inference - As mentioned before, Bayesian inference is more or less always based on summarizing the posterior distribution on one way or the other - Among the most often used methods are: - Estimation Approach (HDI, ROPE, etc.) - Model Comparison Approach (Bayes Factor) --- # Highest density interval (HDI) .pull-left[ - The highest density (sometimes also HCR = Highest density region or HCI = Highest credibility interval) indicates which points of a distribution are most credible/probable. - In other words, it specifies those values that cover most of the distribution - Similarly to Confidence Intervals (CI), we can use the HDI to conclude whether a certain value is outside of this interval to reject e.g. a null hypothesis (yet also any other value!!!) ] .pull-right[ <img src="slides_01_files/figure-html/unnamed-chunk-49-1.png" width="100%" /> ] --- # Highest density interval (HDI) <img src="slides_01_files/figure-html/unnamed-chunk-50-1.png" width="100%" /> - In contrast to frequentist confidence intervals, HDIs are not bound to asymptotic assumptions - Bayesian inference thus works on any type of posterior distribution! --- # Computing HDIs with `bayestestR` .pull-left[ ```r library(insight) library(bayestestR) # Get posterior distributions posteriors <- get_parameters(m_bay) head(posteriors) ``` ``` b_Intercept b_perceptions_std sigma 1 0.29241438 0.4591461 1.0470352 2 0.03768918 0.5339086 1.0149198 3 0.04057643 0.5494236 1.1121559 4 0.02807113 0.5173297 0.9601265 5 0.04294049 0.4668896 0.9556865 6 -0.12552462 0.3730317 0.9448149 ``` ```r # Get HDIs of different widths hdis <- bayestestR::hdi(posteriors$b_perceptions_std, ci = c(.75, .90, .95, .99)) hdis ``` ``` Highest Density Interval 75% HDI | 90% HDI | 95% HDI | 99% HDI --------------------------------------------------------- [0.29, 0.52] | [0.25, 0.58] | [0.19, 0.59] | [0.14, 0.65] ``` ] .pull-right[ ```r plot(hdis) + geom_vline(xintercept = mode_hdi(posteriors$b_perceptions_std)$y, color = "blue", size = 2) + labs(subtitle = "Blue line represents mode of the posterior") + theme_tidybayes() ``` <img src="slides_01_files/figure-html/unnamed-chunk-52-1.png" width="100%" /> ] --- # Region of practical equivalence (ROPE) .pull-left2[ - Indicates a small range of parameter values that are considered to be practically equivalent to the null value for purposes of the particular application (Kruschke, 2015, p. 336) - Once a ROPE is set, we make a decision to reject the NULL if the entire ROPE lies outside the 95% HDI of the posterior distribution - Yet we can also turn the decision rule around: A parameter value is accepted if the value's ROPE completely contains the 95% of the posterior ] .pull-right2[ <img src="slides_01_files/figure-html/unnamed-chunk-53-1.png" width="100%" /> ] --- # Computing ROPES with `bayestestR` .pull-left4[ ```r library(bayestestR) describe_posterior(m_bay, test = c("ROPE"), rope_range = c(-.25, .25)) ``` ``` Summary of Posterior Distribution Parameter | Median | 95% CI | ROPE | % in ROPE | Rhat | ESS -------------------------------------------------------------------------------------- (Intercept) | -0.03 | [-0.24, 0.17] | [-0.25, 0.25] | 100% | 1.001 | 3542.00 perceptions_std | 0.40 | [ 0.20, 0.59] | [-0.25, 0.25] | 4.82% | 1.001 | 4415.00 ``` ] .pull-right4[ ```r ropes <- rope(m_bay, range = c(-.25, .25), ci = .95) plot(ropes) + xlim(-.5, .8) + geom_vline(xintercept = 0, linetype = "dotted") + scale_fill_brewer(palette = "Reds") + theme_tidybayes() + labs(fill = "HDI") ``` <img src="slides_01_files/figure-html/unnamed-chunk-55-1.png" width="100%" /> ] --- # Probability of direction (PD) .pull-left[ - At times, we may want to know if an effect is positive or negative (akin to the frequentist null hypothesis significance test) - In this case, we can also simply compute the proportion of a posterior distribution that is positive, no matter the "size" of the effect (I think you already see the limited use of this... ) - The calculation of this probability is rather simple: We count the number of values below or above 0 (or whatever value we consider our NULL) and devide it by the number of all values in the posterior distribution ] .pull-right[ ```r n_positive <- nrow(filter(posteriors, b_Intercept < 0)) pd <- n_positive / nrow(posteriors) * 100 pd ``` ``` [1] 61.975 ``` There is also a convenient function in the `bayestestR` package that does this for us: ```r p_direction(posteriors$b_Intercept) ``` ``` Probability of Direction: 0.62 ``` ] --- # Relationship with the frequentist p-value .pull-left[ - Beyond its simplicity of interpretation, understanding and computation, this index also presents other interesting properties: - It is independent from the model: It is solely based on the posterior distributions and does not require any additional information from the data or the model. - It is robust to the scale of both the response variable and the predictors. - It is strongly correlated with the frequentist p-value, and can thus be used to draw parallels and give some reference to readers non-familiar with Bayesian statistics. **Note:** However, this index is not relevant to assess the magnitude and importance of an effect, which is (of course) better achieved through other indices such as the ROPE percentage. ] .pull-right[ ```r onesided_p <- 1 - pd / 100 twosided_p <- onesided_p * 2 twosided_p ``` ``` [1] 0.7605 ``` ```r summary(m_freq)$coef[1,] ``` ``` Estimate Std. Error t value Pr(>|t|) -0.0317826 0.1000143 -0.3177806 0.7513715 ``` ] --- # Posterior predictive checks .pull-left2[ - Posterior predictive checks refers to "simulating replicated data under the fitted model and then comparing these to the observed data" (Gelman and Hill, 2007, p. 158) - We can thus use posterior predictions to look for systematic discrepancies between real and simulated data ```r library(bayesplot) pp_check(m_bay, ndraws = 100) + theme_tidybayes() ``` ] .pull-right[ <img src="slides_01_files/figure-html/pp-out-1.png" width="100%" /> ] --- class: inverse, center, middle # Subjective Beliefs and Knowledge Cumulation "Understanding and quantifying prior beliefs" --- # Prior vs. Posterior in our example .pull-left[ ```r m_bay2 <- brm(formula = behavior_std ~ 1 + perceptions_std, prior = c(prior(normal(0, 10), class = "Intercept"), prior(normal(0, 10), class = "b")), sample_prior = T, data = d[1:100,], seed = 2) save(m_bay2, file = "slides/material/results/m_bay2.RData") ``` ```r load("material/results/m_bay2.RData") plotPriorPost <- function(model, effect) { effect <- enquo(effect) # Get prior and posterior samples posteriors3 <- get_parameters(model) %>% as_tibble %>% mutate(type = "posterior") priors3 <- prior_draws(model) %>% as_tibble %>% magrittr::set_colnames(names(posteriors3)) %>% mutate(type = "prior") # Plot bind_rows(posteriors3, priors3)%>% ggplot(aes(x = !! effect, fill = type)) + geom_density(alpha = .8) + theme_tidybayes() + theme(legend.position = "top") + labs(x = expr(theta), y = "", fill = "") + scale_fill_manual(values = c("steelblue", "grey")) } plotPriorPost(m_bay2, b_perceptions_std) + xlim(-5, 5) ``` ] .pull-right[ <img src="slides_01_files/figure-html/prior1-out-1.png" width="100%" /> ] --- # Quantifying prior beliefs as distribution .pull-left[ - A central aspect of Bayesian statistics and particular when working with regression models refers to "quantifying" prior beliefs as a distribution of probable parameter ($\theta$). - We already talked about this earlier (remember the coin toss example), but let's again revisit this central idea. - In most cases, we may think of a parameter distribution as a normal distribution (which we can easily specify in R and in Stan). ```r dnorm(x, 0, 1) # R normal(0, 1) # Stan ``` - Our best guess is then the mean of the distribution, our uncertainty is represented by the standard deviation. ] .pull-right[ <img src="slides_01_files/figure-html/unnamed-chunk-62-1.png" width="100%" /> ] --- # Our beliefs do not necessarily have to be normally distributed... .pull-left[ - In some cases, it may make sense to not use a normal distribution, e.g., if we want to indicate our strong belief that the effect should be positive - Technically, any prior is possible, the difficulty is to justify it based on existing literature! ] .pull-right[ <img src="slides_01_files/figure-html/unnamed-chunk-63-1.png" width="100%" /> ] --- # So what about a bit more information for our example? .pull-left[ - It should have been obvious that a weakly informative prior (the default) is hardly appropriate - For example, a meta analysis by Rains et al. (2018) of 60 years of communication research suggest an average effect of r = 0.2. Why not include this prior information in the model? - We keep the distribution fairly wide, but I think we can all agree that values > .5 are rather unlikely. ] .pull-right[ <img src="slides_01_files/figure-html/prior2-out-1.png" width="100%" /> ] --- # Model with a bit more informative priors .pull-left[ ```r m_bay3 <- brm(formula = behavior_std ~ 1 + perceptions_std, prior = c(prior(normal(0, 5), class = "Intercept"), prior(normal(0.2, 0.5), class = "b")), sample_prior = T, data = d[1:100,], seed = 2) save(m_bay3, file = "slides/material/results/m_bay3.RData") ``` ```r load("material/results/m_bay3.RData") plotPriorPost(m_bay3, b_perceptions_std) ``` ] .pull-right[ <img src="slides_01_files/figure-html/prior3-out-1.png" width="100%" /> ] --- # Why the hassle? ```r # Weakly informative describe_posterior(m_bay2, test = "ROPE") ``` ``` Summary of Posterior Distribution Parameter | Median | 95% CI | ROPE | % in ROPE | Rhat | ESS -------------------------------------------------------------------------------------- (Intercept) | -0.03 | [-0.24, 0.18] | [-0.10, 0.10] | 69.18% | 1.001 | 3726.00 perceptions_std | 0.40 | [ 0.20, 0.60] | [-0.10, 0.10] | 0% | 1.000 | 4208.00 ``` ```r # Mildly informative describe_posterior(m_bay3, test = "ROPE") ``` ``` Summary of Posterior Distribution Parameter | Median | 95% CI | ROPE | % in ROPE | Rhat | ESS -------------------------------------------------------------------------------------- (Intercept) | -0.03 | [-0.23, 0.17] | [-0.10, 0.10] | 71.18% | 0.999 | 3668.00 perceptions_std | 0.39 | [ 0.20, 0.58] | [-0.10, 0.10] | 0% | 1.000 | 4027.00 ``` --- # Cumulative knowledge - Let's investigate the effect of the norm manipulations (0%, 20% or 80% of the posts in the social media feed showed "faces") on norm perceptions related to visual disclosure - Let's further imagine we would have conducted the experiment 4 times with n = 100 each. - Here is a visual representation of the data from the first study .pull-left[ ```r library(see) ggplot(d[1:100,], aes(x = norm, y = perceptions, fill = norm)) + geom_violindot() + theme_tidybayes() + scale_y_continuous(n.breaks = 7) + scale_fill_brewer(palette = "Blues") + labs(x = "Norm Manipulations", y = "Norm Perceptions") + theme(legend.position = "none") ``` ] .pull-right[ <img src="slides_01_files/figure-html/prior5-out-1.png" width="100%" /> ] --- # Stepwise updating with more data ```r d$norm_n <- as.numeric(as.factor(d$norm)) step1 <- brm(formula = perceptions ~ 1 + norm_n, prior = c(prior(normal(0, 10), class = "Intercept"), prior(normal(1, 3), class = "b"), prior(uniform(0, 10), class = "sigma")), sample_prior = T, data = d[1:100,], seed = 2) step2 <- brm(formula = perceptions ~ 1 + norm_n, prior = c(prior(normal(1.81, 0.40), class = "Intercept"), prior(normal(1.40, 0.18), class = "b"), prior(normal(1.35, 0.10), class = "sigma")), init = 1.3, sample_prior = T, data = d[101:200,], seed = 2) step3 <- brm(formula = perceptions ~ 1 + norm_n, prior = c(prior(normal(1.07, .26), class = "Intercept"), prior(normal(1.50, .11), class = "b"), prior(normal(1.23, .07), class = "sigma")), sample_prior = T, data = d[201:300,], chains = 2, cores = 2, seed = 2) step4 <- brm(formula = perceptions ~ 1 + norm_n, prior = c(prior(normal(0.63, .21), class = "Intercept"), prior(normal(1.53, .08), class = "b"), prior(normal(1.26, .06), class = "sigma")), sample_prior = T, data = d[201:300,], chains = 2, cores = 2, seed = 2) save(step1, step2, step3, step4, file = "slides/material/results/examples.RData") ``` --- # Bayesian Updating <img src="slides_01_files/figure-html/unnamed-chunk-68-1.png" width="100%" /> -- - Within a Bayesian framework, we can connect findings of consecutive studies to gain more and more understanding of the parameter of interest - Over time, we might even reach a point at which the data doesn't contribute any additional information to the prior (study 4) --- # Comparison of results ``` Summary of Posterior Distribution Parameter | Median | 95% CI | pd | ROPE | % in ROPE | Rhat | ESS ---------------------------------------------------------------------------------------- (Intercept) | 1.81 | [1.04, 2.57] | 100% | [-0.17, 0.17] | 0% | 0.999 | 4427.00 norm_n | 1.40 | [1.04, 1.75] | 100% | [-0.17, 0.17] | 0% | 0.999 | 4515.00 ``` ``` Summary of Posterior Distribution Parameter | Median | 95% CI | pd | ROPE | % in ROPE | Rhat | ESS ---------------------------------------------------------------------------------------- (Intercept) | 1.07 | [0.54, 1.57] | 100% | [-0.17, 0.17] | 0% | 0.999 | 3786.00 norm_n | 1.50 | [1.28, 1.73] | 100% | [-0.17, 0.17] | 0% | 1.000 | 3915.00 ``` ``` Summary of Posterior Distribution Parameter | Median | 95% CI | pd | ROPE | % in ROPE | Rhat | ESS ------------------------------------------------------------------------------------------ (Intercept) | 0.63 | [0.23, 1.04] | 99.80% | [-0.17, 0.17] | 0% | 1.000 | 1780.00 norm_n | 1.53 | [1.35, 1.70] | 100% | [-0.17, 0.17] | 0% | 0.999 | 1789.00 ``` ``` Summary of Posterior Distribution Parameter | Median | 95% CI | pd | ROPE | % in ROPE | Rhat | ESS ------------------------------------------------------------------------------------------- (Intercept) | 0.16 | [-0.21, 0.52] | 79.65% | [-0.17, 0.17] | 51.89% | 1.000 | 1667.00 norm_n | 1.54 | [ 1.40, 1.68] | 100% | [-0.17, 0.17] | 0% | 1.001 | 1669.00 ``` --- # Cumulative evidence, better estimation .pull-left[ - As we can see clearly in the figure on the right, the estimation of the parameter of interest becomes better and better - After all, we are using information from 4 studies in the last step - Priors based on past studies thus improve the model and the estimation ] .pull-right[ <img src="slides_01_files/figure-html/unnamed-chunk-70-1.png" width="100%" /> ] --- class: inverse, center, middle # Wrap Up and Conclusions "What are we talking about?" --- # Summary: Steps of Bayesian Data Analysis 1. Identify the **data relevant to the research questions**. What are the measurement scales of the data? Which data variables are to be predicted, and which data variables are supposed to act as predictors? 2. Define a **descriptive model** (likelihood) for the relevant data. The mathematical form and its parameters should be meaningful and appropriate to the theoretical purposes of the analysis. 3. Specify **prior distributions** for the parameters. The prior must pass muster with the audience of the analysis, such as skeptical scientists. In case of doubt, a weakly informative prior is always a good choice. 4. Use Bayesian inference to **re-allocate credibility** across parameter values. Interpret the posterior distribution with respect to theoretically meaningful issues (Estimation Approach). 5. Check whether **MCMC chains converged** and that the **posterior predictions** mimic the data with reasonable accuracy. If not, then consider a different descriptive model. --- # Bayes Benefits I: Prior Beliefs .pull-left2[ <img src="slides_01_files/figure-html/unnamed-chunk-71-1.png" width="100%" /> ] .pull-right2[ - It makes us think more clearly about our prior beliefs - Specifying priors for our parameters of interest forces us to scrutinize our own assumptions - How strongly do you believe in your own hypothesis? Enough to quantify it as a strong prior? - Is there indeed sufficient (high-quality) previous research to justify the hypothesis/prior? - Forces us to consider the state of prior knowledge - Allows for cumulative knowledge creation (so far not really done!) ] --- # Bayes Benefits II: No constraints for model specification .pull-left[ - Bayesian modelling is not bound to any particular assumptions (compared to Frequentist statistics) - Particularly `brms` supports a wide (and I mean really wide!) set of models and families - Whenever `lmer()` breaks, simply use `brm()` and you will get a result ] .pull-right[  ] --- # Bayes Benefits III: Thinking more clearly about our inferences .pull-left[ <img src="slides_01_files/figure-html/unnamed-chunk-72-1.png" width="100%" /> ] .pull-right[ <img src="slides_01_files/figure-html/unnamed-chunk-73-1.png" width="100%" /> ] --- # Conclusion .pull-left[ ### Advantages - Intuitive approach to expressing and quantifying uncertainty - Ability to incorporate prior information - More modeling flexibility - Posterior distribution sof parameters - Cumulative knowledge creation and thus natural propagation of uncertainty ] .pull-right[ ### Disadvantages - Slow in estimating models (but soon we all work with super computers anyways, no?) ] --- # How to report Bayesian results .pull-left4[ - Overall similar to standard model reporting, but additional consider: - Justify the use of Bayesian methods (reiterate benefits over other approaches, motify the use of prior) - Clearly describe data structure, model, and parameter - Sufficiently describe the chosen priors and justify them - Report MCMC details (convergence of chains, length of chains, ESS) - Comprehensive interpretation of the posterior (driven by research questions/hypotheses) ] .pull-right4[  ] --- class: inverse, center, middle # Let's practice in R! Perhaps it will turn you into a "Bayesian"... --- # Literature - Dilipkumar, D. (2021). *Frequentist and Bayesian Inference.* https://towardsdatascience.com/frequentist-and-bayesian-inference-83af2595f172 - Jackman, S. (2009). *Bayesian Analysis for the Social Science.* Wiley. - Kurz, S. (2022). *Doing Bayesian Data Analysis in brms and the tidyverse* (version 1.0.0). Retrieved from https://bookdown.org/content/3686/ - Kurz, S. (2022). *Statistical Rethinking with brms, ggplot2, and the tidyverse* (version 1.0.1). Retrieved from https://bookdown.org/ajkurz/Statistical_Rethinking_recoded/ - Kruschke, J. (2015). *Doing Bayesian Data Analysis. A Tutorial Introduction with R.* Elsevier Science. - McElreath, R. (2020). *Statistical Rethinking: A Bayesian Course with Examples in R and Stan* (Second Edition). CRC Press.